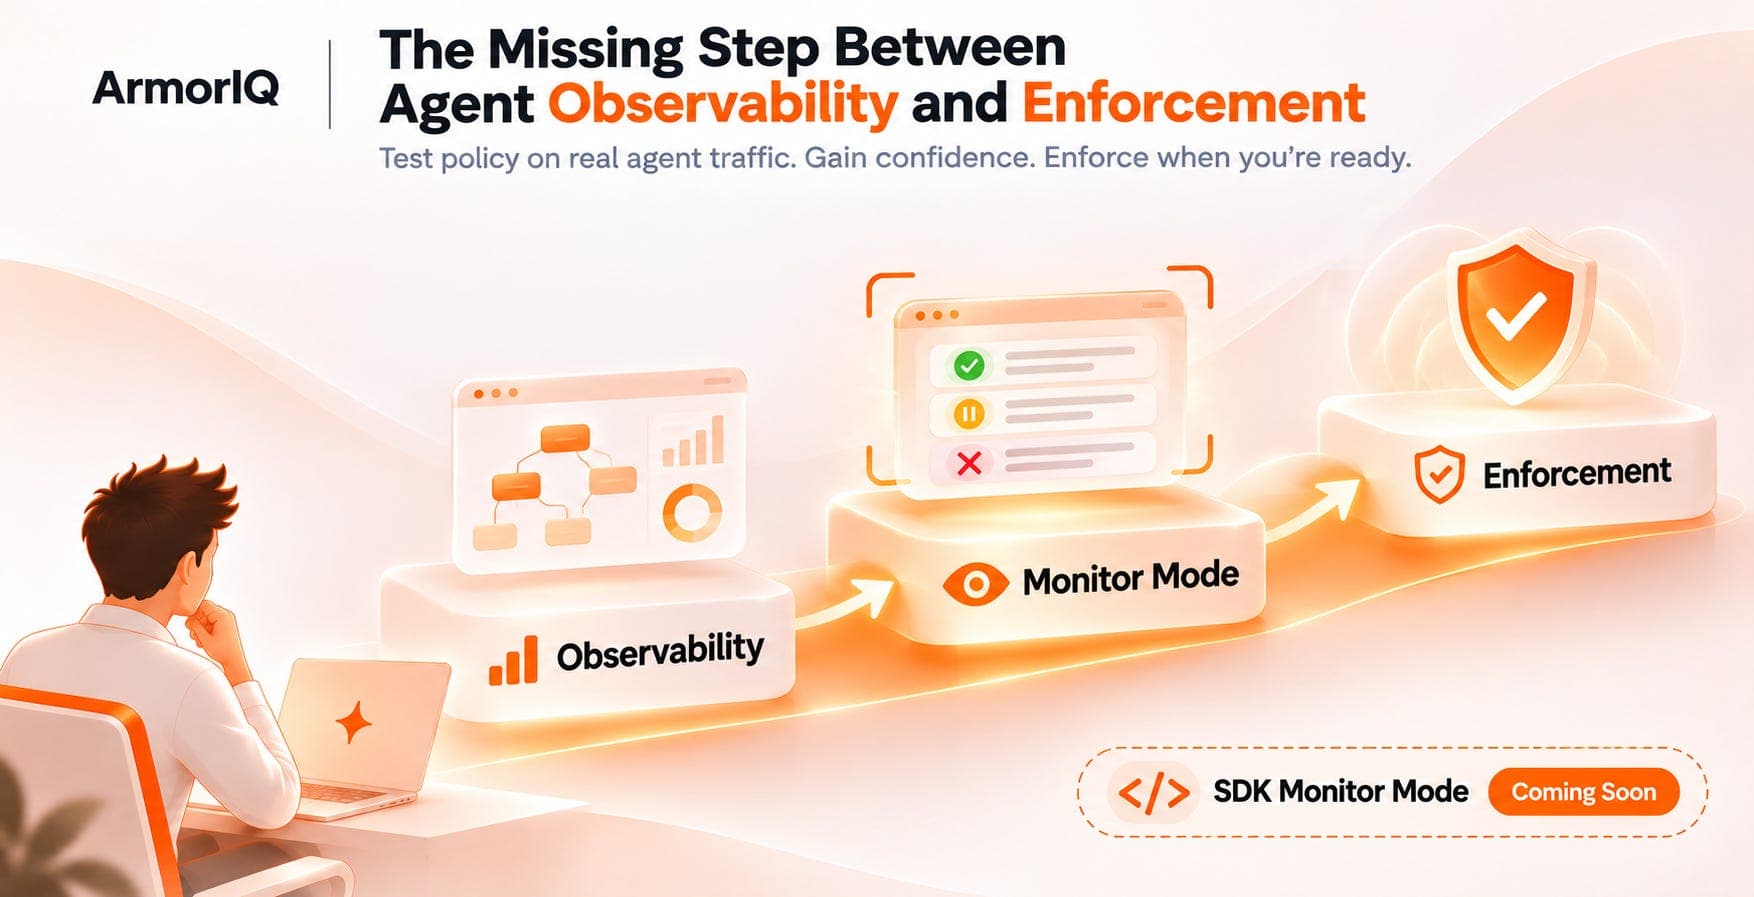
Agent security is often framed as a deployment choice: SDK or gateway. The accompanying video shows why that question is too small. The real issue is that an agent moves through two distinct paths, and most controls are positioned to see only one of them.
The first is the reasoning path. Context, instructions, available tools, and observations go to the model, and the model proposes what should happen next. The second is the execution path. The agent takes those proposals and turns them into tool calls, function calls, API requests, file writes, process launches, and other effects.
From the outside these paths look like one continuous flow. They are not. Between them sits the agent loop: framework code, retries, argument transformations, local functions, tool results, and new context accumulated while the task is running. That middle layer is useful precisely because it is allowed to adapt. It is also where reasoning and execution can diverge.
So the security problem is not simply whether a proposed action looks safe, or whether an executed tool call matches a static policy. It is whether the execution path remains faithful to the reasoning that was actually authorized, and whether the mechanism making that judgment lives somewhere the agent cannot quietly remove.
The reasoning path is not the execution path
The reasoning path is the easiest place to understand what the model decided. The agent provides the situation and the available tools; the model returns a plan or a set of proposed calls. A gateway on this path can inspect that response before the agent receives it. If a proposed payment violates policy, the gateway can remove it. The agent cannot execute a call it was never handed.
That is a strong control, and it is operationally attractive because it can often be introduced without changing the agent. A base URL changes, traffic flows through the gateway, and the model response is now subject to policy.
But the gateway’s knowledge ends when the response is handed back to the agent. The agent loop can still retry, normalize, enrich, or alter what happens next. Imagine the model proposes send_payment(amount=500), while the agent eventually executes send_payment(amount=50000). Or the model proposes only a bill lookup and framework logic later adds a payment call. The reasoning gateway did its job correctly. It simply never saw the final effect.
Moving enforcement to the execution path gives us the opposite view. Put a gateway in front of MCP servers or APIs and now we see exactly what leaves the agent. We can block a dangerous tool, constrain arguments, or apply enterprise policy to each call. What this position does not know by itself is whether that exact call was ever part of the reasoning that the model produced.
This is why the video introduces the second security level by guarding both network paths. One side observes the model’s proposed plan. The other observes the later tool call. When every consequential action really does cross those boundaries, the system can reconnect reasoning and execution without modifying the agent.
The qualification matters. Agents are not made entirely of network calls. A Python function can issue a refund, query a database handle, modify local state, or invoke application logic without producing an HTTP request or an MCP round trip. Real agents mix remote integrations with local functions all the time. A network control plane can be excellent and still have no visibility into that part of execution.
That is not a gateway failure. It is a property of the trust boundary.
Reconnecting the two paths
An in-process SDK occupies a different position because it can see both sides of the transition. It can observe the model response as it arrives and wrap the dispatch path through which the agent invokes tools, including local functions that never leave the process.
That changes the question we can ask. Instead of asking only whether a tool is generally allowed, we can ask whether this exact action is part of the exact plan that was accepted for this task.
ArmorIQ can capture and canonicalize the plan, commit it, and associate it with a signed token. Each subsequent action is checked against that commitment. If the model proposed 500 and the runtime attempts 50,000, the later call is not rescued by the fact that payments may be broadly permitted. It fails because it is not the action that was committed.
This is a much stronger form of continuity. It covers network tools and local functions, and it distinguishes ambient permission from task-specific authority. The agent may possess a capability without being authorized to exercise it in every execution.
But moving visibility into the process creates a new trust problem. The SDK lives with the agent. If the agent can remove the import, uninstall the package, replace the dispatcher, or route around the check, then we have solved the observation problem without solving the enforcement problem.
Capture where the semantics are visible. Enforce where the agent cannot tamper.
This is where the SDK-versus-gateway framing breaks down. The best place to understand the transition from reasoning to execution is often inside the agent, but the final authority over that transition does not have to live there.
The in-process component can commit the plan and attach a signed token to the later action. An independent enforcement point, outside the agent’s control, verifies both the token and the requested step before allowing the tool to run. The agent proposes the action; the control plane decides whether the proof is sufficient.
Now remove the SDK and the failure mode changes. No plan is committed. No valid token exists. The downstream verifier does not treat missing proof as permission. It refuses the action. Removing the guard no longer opens the door; it removes the credential required to get through it.
This is the central idea behind the accompanying video. Capture where the agent’s semantics are visible, but enforce where the agent cannot rewrite the decision.
The three levels are really three trust assumptions
The security levels in the video are best understood as progressively removing assumptions rather than progressively adding products.
At the first level, we can govern the model’s proposed reasoning, but we trust the agent loop to carry that reasoning into execution faithfully. At the second, we observe both network paths and can compare the proposed plan with the resulting tool calls, but we assume every consequential action actually crosses those gateways. At the third, we also observe local dispatch, closing the gap created by in-process functions and framework logic.
The independent verifier removes one more assumption: that the agent will voluntarily keep its own guard installed.
This does not mean every deployment needs the same integration. A gateway-only architecture can be exactly right when agent code cannot change and every consequential action is already behind a controllable interface. But the conclusion depends on those facts remaining true. Add one local function with a database handle and the security boundary changes even if the policy configuration does not.
The useful design question is therefore not which product should I deploy. It is what assumptions am I still making about the path from model reasoning to machine effect.
From two paths to intent continuity
For ArmorIQ, the reasoning path and execution path are a concrete way to describe a larger problem: intent continuity.
A model’s plan is not yet an effect. An executed tool call is not automatically evidence that the model intended it. A trustworthy system has to preserve the lineage between the two.
That is what the Intent Assurance Plane is designed to do. The accepted plan becomes a committed object, and later actions must remain derivable from it. We do not need to make the model deterministic. We need the boundary around what the model is allowed to turn into action to be deterministic.
The same reasoning continues below the agent runtime. A tool call may spawn a process, which reads a file, opens a socket, or invokes another service. When a boundary has to survive those transitions, enforcement can move farther down into a sandbox or Kernel Assurance. The representation becomes more concrete, but the authority still originates from the same accepted intent.
Seen this way, the video is not really comparing three product configurations. It is showing three stages in a trust architecture. We first gain visibility into reasoning and execution. Then we reconnect them with a verifiable commitment. Finally, we ensure that the component enforcing that commitment sits outside the authority of the thing being governed.
SDK or gateway is an implementation choice inside that architecture. Sometimes one is enough. Often both are useful. In higher-assurance environments, the boundary may need to extend below either of them.
The durable principle is simpler: an autonomous agent should not be able to turn a difference between what it reasoned about and what it executed into an invisible expansion of authority. Security has to see both paths, preserve the connection between them, and fail closed when that connection disappears.